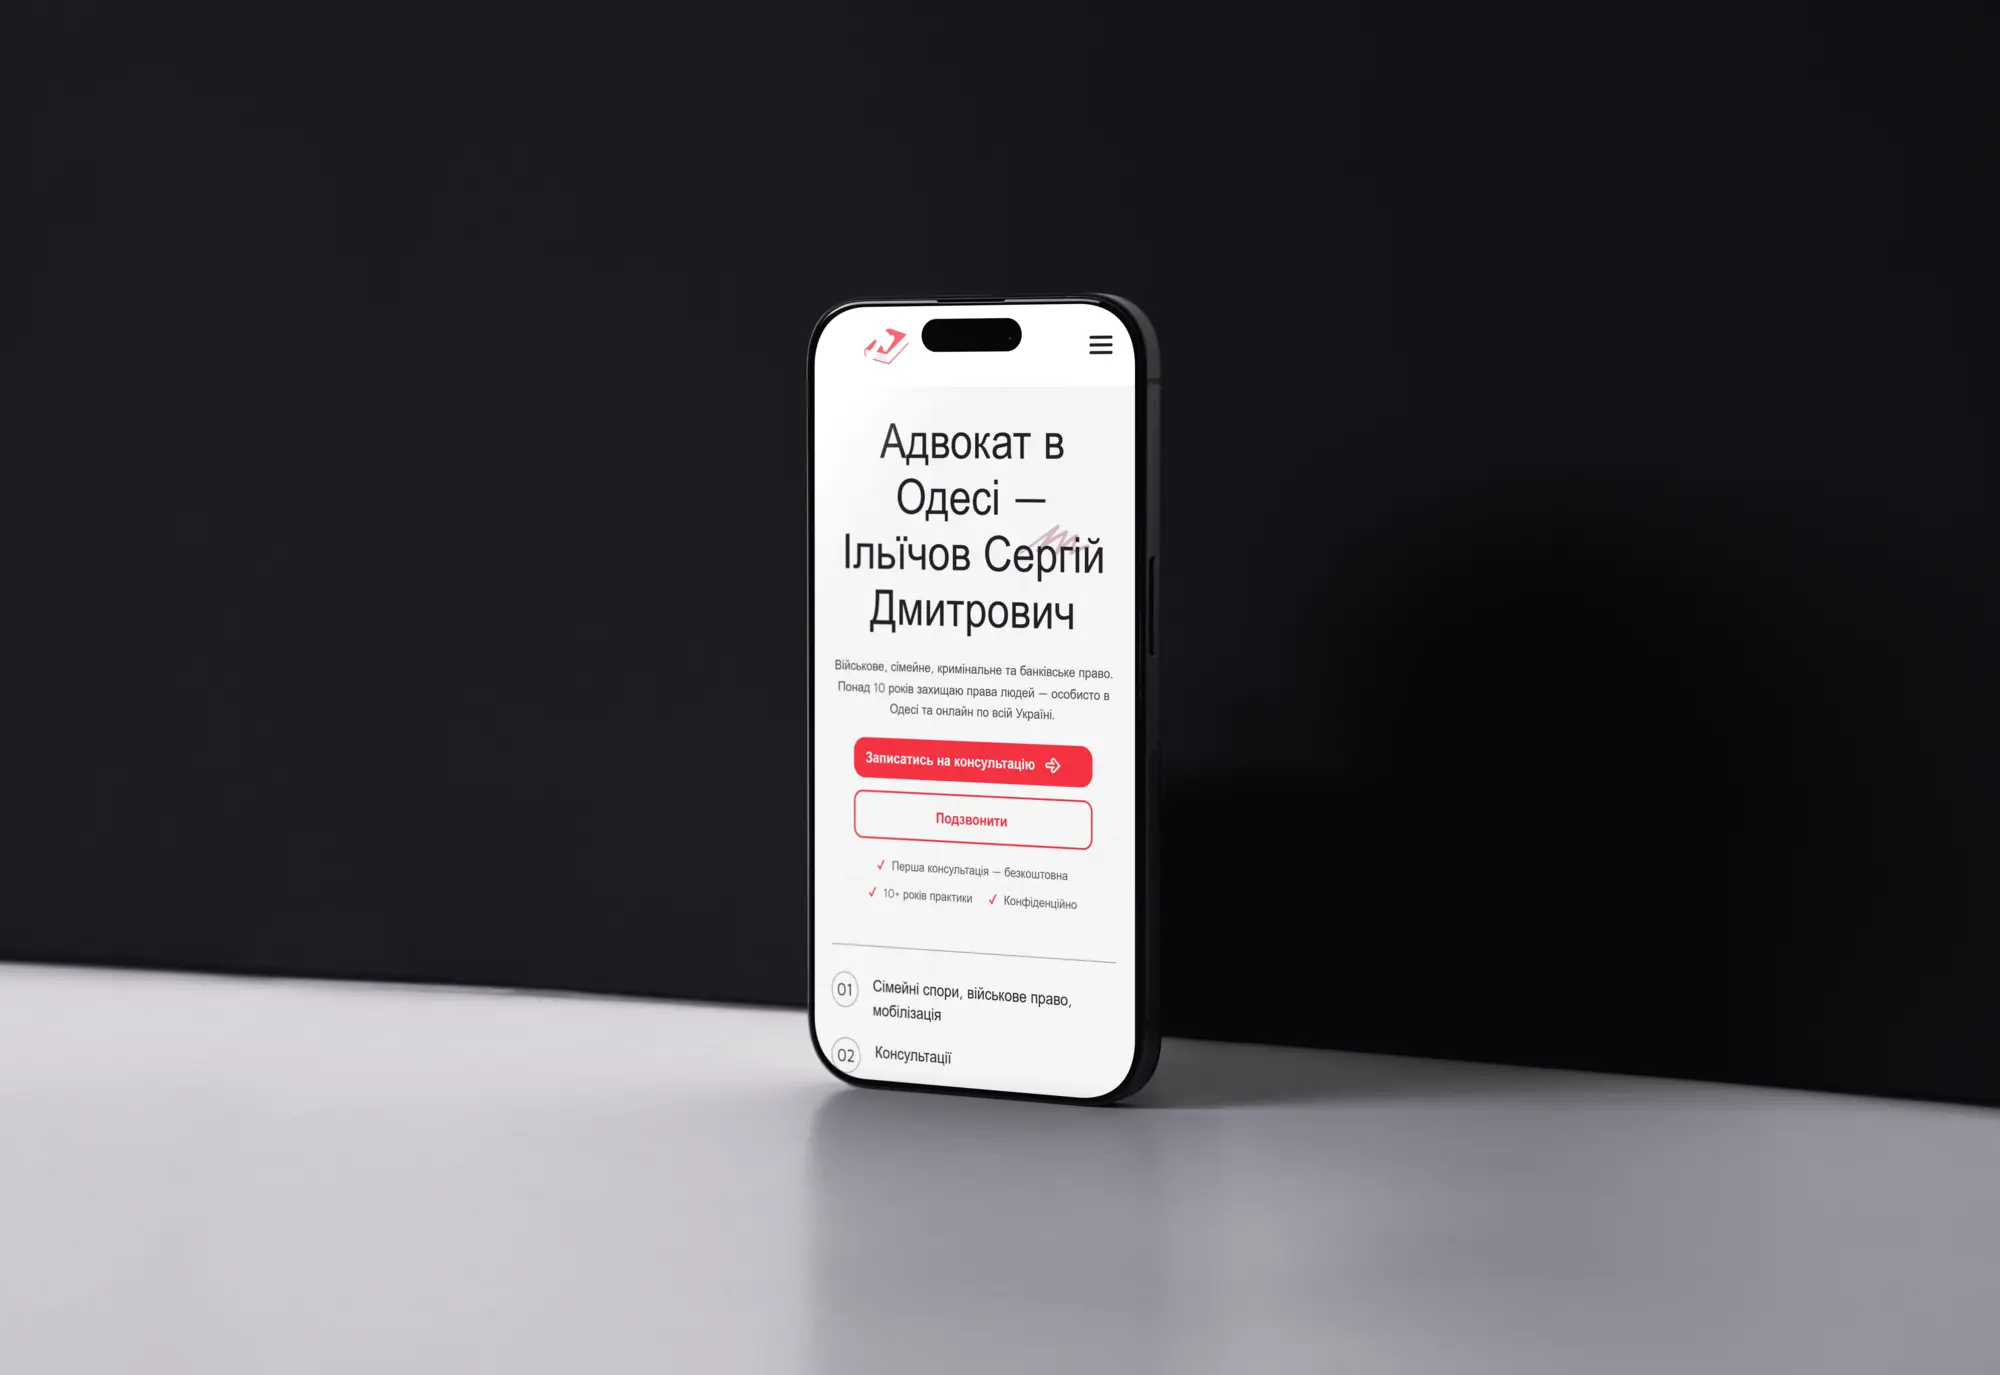
NEW CASE
Antana

We create digital solutions that work for businesses


Give us a call +38 (066) 35-14-529

Let's take the first step towards your website — write to us

Close
Tools

AI Crawler Checker

Whether your robots.txt lets GPTBot, ClaudeBot and PerplexityBot in.

Why check AI crawler access

Language models draw answers from sites they are allowed to read. Block them and you will not be cited; allow them and your content may be used for training.

Allow

When to let them in

  • You want to be cited in answers
  • You publish expert material
  • You sell services people look for in chat
vs
Block

When to block

  • Content is your product
  • Licensed material or third-party rights
  • Data that should not spread

Worth being clear: allowing AI crawlers does not improve ordinary search rankings. These are separate things, and claims to the contrary deserve scepticism.

Who these crawlers are

One company may run several crawlers with different purposes. Blocking one does not block them all.
GPTBot OpenAI, gathering data to train models. The one most often blocked.
OAI-SearchBot Also OpenAI, but for search inside ChatGPT. Blocking it means disappearing from those answers.
ClaudeBot Anthropic, model training. Separately there is Claude-User, for following a link during a conversation.
PerplexityBot Perplexity indexes pages and shows sources with links in its answers.
Google-Extended Not a separate crawler but a switch: it permits or forbids using content to train Gemini. Ordinary search is unaffected.
CCBot Common Crawl is an open archive many companies draw data from at once.

Configuration mistakes

Blocked one of a pair GPTBot blocked, OAI-SearchBot left open. Your content will not be used for training but you stay in ChatGPT search — often exactly what was wanted, provided you know the difference.
A rule after the * group If a crawler has its own group, the * rules do not apply to it at all. It replaces rather than adds.
A typo in the crawler name GPT-Bot instead of GPTBot and the rule does nothing. Names must match exactly what the vendor publishes.
robots.txt returns something other than 200 A server error instead of the file means there are no rules at all. Most crawlers treat that as permission for everything.

How to change access

1 Decide what you are blocking Model training and appearing in answers are different things. Often it makes sense to block the first and keep the second.
2 Add a separate group A User-agent line with the crawler name, then Disallow beneath it. Each crawler needs its own group; they cannot share one.
3 Verify the result Run the site through this check again. A single wrong character silently makes a rule useless.
4 Remember what robots.txt cannot do It is a request, not a server-level block. Well-behaved crawlers honour it; others do not. Real protection needs other means.

FAQ

Does allowing AI crawlers affect Google rankings?
No. These are separate systems: Googlebot handles ordinary search while Google-Extended covers model training. You can block the latter and stay in search, or the reverse. Claims that llms.txt or open AI crawlers lift your rankings have no basis.
Does blocking GPTBot remove me from ChatGPT?
Not necessarily. GPTBot gathers training data while OAI-SearchBot powers search inside ChatGPT — different crawlers. Blocking the first keeps you out of the training set but leaves you in cited answers. That is often exactly what people want.
Are crawlers obliged to obey robots.txt?
It is a convention, not a technical block. Major companies honour it and publish their crawler names. Smaller scrapers often do not. Real protection needs server-level rules, not a text file.
Why does it say the robots.txt could not be read?
The server returned something other than 200 — often a 403 when protection blocks automated requests. That differs from the file being absent: any conclusion about crawler access would be premature, and we say so in the result.
How do I block every AI crawler at once?
There is no single rule for all: each company uses its own crawler name, so every one needs its own User-agent group. The wildcard rule applies only when a crawler has no group of its own.
Telegram Viber Call us